Yao Ji

Yao Ji

H. Milton Stewart Postdoctoral Fellow

H. Milton Stewart School of Industrial and Systems Engineering

Georgia Institute of Technology · Atlanta, GA

Beyond research

Operations Researcher

I am an H. Milton Stewart Postdoctoral Fellow in the H. Milton Stewart School of Industrial and Systems Engineering at Georgia Tech mentored by Prof. Guanghui (George) Lan.
My research develops optimization algorithms with optimal convergence rates for machine learning and reinforcement learning. My work centers on the design and complexity analysis of deterministic and stochastic optimization methods, with a current focus on parameter-free algorithms that adapt to unknown problem structure. For machine learning, I develop scalable stochastic methods that require no stepsize tuning. For reinforcement learning, I develop efficient methods for online policy evaluation. Healthcare is a major application domain for both research directions.
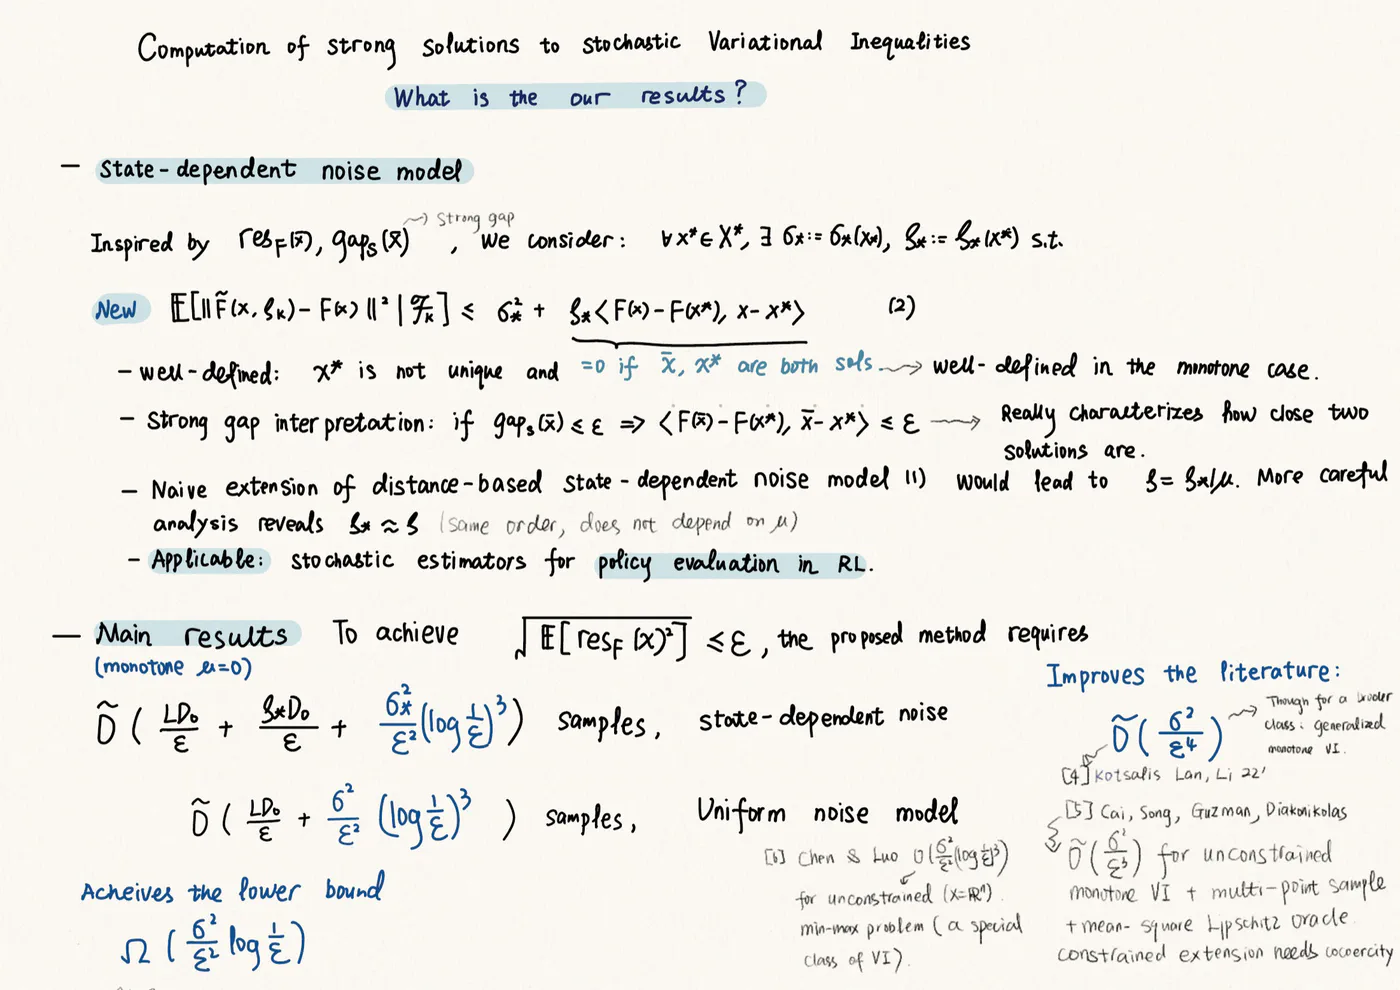
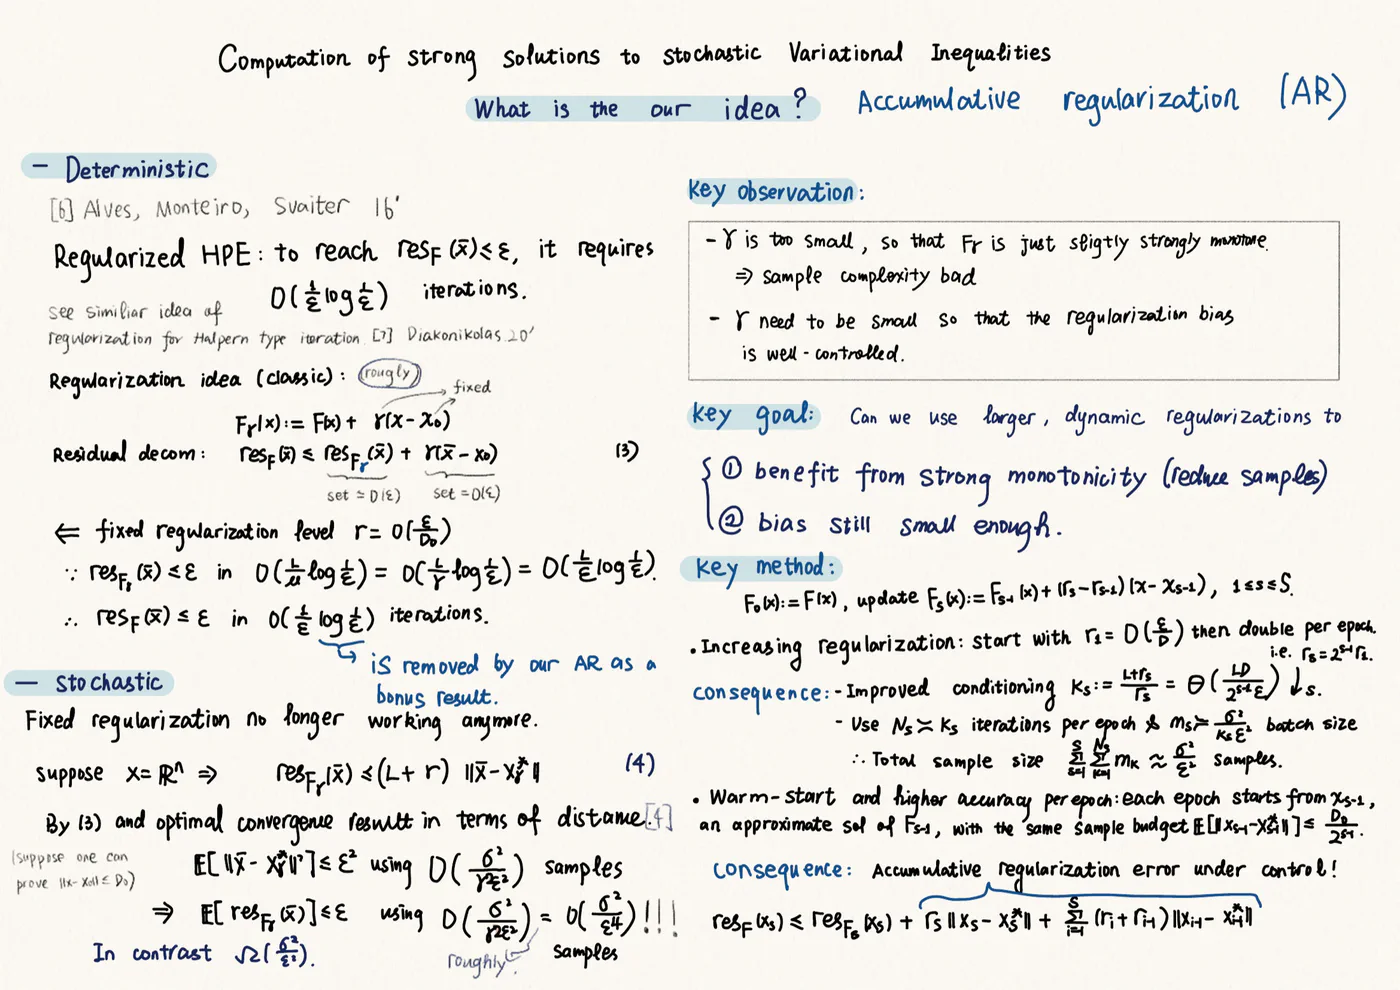
Research roadmapA fishbone roadmap whose spine is optimization for machine learning and reinforcement learning. Where it starts: distributed statistical learning (Ji et al., 2023, 2023, 2024). The core, parameter-free optimization: high-order methods (Ji and Lan, 2025), stochastic AC-FGM (Ji and Lan, 2026), and strong solutions to variational inequalities (Ji, Lan and Zhu, 2026), which branches into long-horizon policy evaluation. In progress: nonconvexity and stochasticity, and optimizer design for machine learning with Siri at Apple. Applications: machine learning and reinforcement learning for healthcare with Cleveland Clinic and Stanford Medicine (Ji, Li, Lan et al., 2026), next extending beyond acute kidney injury and perioperative procedures. Next: structural refinement, optimization for reinforcement learning, and large-scale post-training.Optimizationfor ML and RL’23’23’24Distributed Statistical LearningJi et al.Parameter-freeoptimizationHigh-orderJi, Lan ’25Stochastic AC-FGMJi, Lan ’26Strong solutions to VIJi, Lan, Zhu ’26long-horizonpolicy evaluationOptimization for RLLarge-scalepost-trainingNonconvexity andstochasticityOptimization for MLOptimizer designSiri at AppleML and RL for healthcareCleveland Clinic, Stanford MedicineJi, Li, Lan et al. ’26Beyond acute kidney injuryand perioperative proceduresStructural refinement

How much global information does an optimization algorithm really need?

Observe partially, perform optimally.

Recent News

Available Fall 2026 academic job market Seeking position in operations research.

Major Revision at Mathematical Programming

Stochastic Auto-conditioned Fast Gradient Methods with Optimal Rates received a major revision from Mathematical …

Paper Submitted to the British Journal of Anaesthesia

Our paper on transformer-based offline reinforcement learning for perioperative kidney risk management in cardiac …

Co-organizing a Session on Stochastic Optimization for RL at INFORMS 2026

Co-organizing Recent Progress in Stochastic Optimization for Reinforcement Learning with Yan Li at the 2026 INFORMS …

Presenting in the INFORMS 2026 Job Market Showcase

Presenting Stochastic Auto-conditioned Fast Gradient Methods with Optimal Rates in the Stochastic and Decentralized …

Co-organizing a Session on Stochastic Optimization at INFORMS 2026

Co-organizing New Advances in Stochastic Optimization, Theories and Methodologies with Hongcheng Liu at the 2026 INFORMS …

Attending ColOpt 2026

Attended ColOpt 2026 at Lehigh University, including a funding-agencies session for early-career researchers.

Talk at MOPTA 2026

Gave a talk on Stochastic Auto-conditioned Fast Gradient Methods with Optimal Rates at MOPTA 2026, Lehigh University.

Co-organizing Two Sessions at MOPTA 2026

Co-organized and co-chaired two sessions on stochastic optimization and variational inequalities with Tianjiao Li at …

Poster at Southern California OR/OM Day

Presented a poster on Stochastic Auto-conditioned Fast Gradient Methods with Optimal Rates at SoCal OR/OM Day, USC …

Seminar at Clemson University

Gave a seminar at Clemson's School of Mathematical and Statistical Sciences on Stochastic Auto-conditioned Fast Gradient …

Field Visit to Gwinnett County Wastewater Facility

Visited the Gwinnett County wastewater facility with collaborators, marking the start of a new project on reinforcement …

Poster Presentation at SCA 2026 in Nashville, Tennessee

Presenting our poster on Transformer-Based Patient Response Modeling for Cardiac Surgery-Associated AKI at SCA 2026.

Chairing a Session at INFORMS Optimization Society Conference 2026

Chairing a session on Accelerated Methods and Sharp Analysis for Nonlinear Optimization at IOS 2026.

See you at INFORMS 2025

Presenting a talk on High-Order Accumulative Regularization for Gradient Minimization at INFORMS 2025.

H. Milton Stewart Postdoctoral Fellow at Georgia Tech

Starting my new role as a postdoctoral fellow at Georgia Tech.

Research Interests and Selected Works

Stochastic optimization; reinforcement learning; healthcare.

Current focus

  • Parameter-Free Optimization
  • Stochastic Optimization
  • Higher-Order Optimization
  • Variational Inequalities
  • Reinforcement Learning
  • Healthcare
  • Distributed Optimization

Foundation

Stochastic Auto-conditioned Fast Gradient Methods with Optimal Rates

Optimal iteration and sample complexities for parameter-free stochastic acceleration.
  • Parameter-Free Optimization
  • Stochastic Optimization

Yao Ji and Guanghui Lan

Mathematical Programming, Series A

arXiv:2604.06525, 2026

Major revision

Algorithm AR framework for gradient minimization

Require: $S$, a strictly increasing sequence $\{\sigma_s\}_{s=0}^{S}$ with $\sigma_0 = 0$, and an initial point $x_0 \in \mathbb{R}^n$.

  1. for $s = 1,\dots,S$ do
  2. Compute an approximate solution $x_s$ of the proximal subproblem $$x_s \approx \operatorname*{arg\,min}_{x \in \mathbb{R}^n} \Big\{\, f_s(x) := f(x) + \textstyle\sum_{i=1}^{s} \tfrac{\sigma_i - \sigma_{i-1}}{p+\nu}\,\|x - x_{i-1}\|^{p+\nu} \Big\}$$ where $p + \nu \geq 2$, by running a subroutine $\mathcal{A}$ initialized at $x_{s-1}$ for $N_s$ iterations.
  3. end for
  4. Output: $x_S$

High-Order Accumulative Regularization for Gradient Minimization in Convex Programming

Optimal gradient complexity for finding points with small gradients.

  • Parameter-Free Optimization
  • Higher-Order Optimization

Yao Ji and Guanghui Lan

SIAM Journal on Optimization

arXiv:2511.03723, 2025

R&R 2nd round review

Learning and Decision-Making

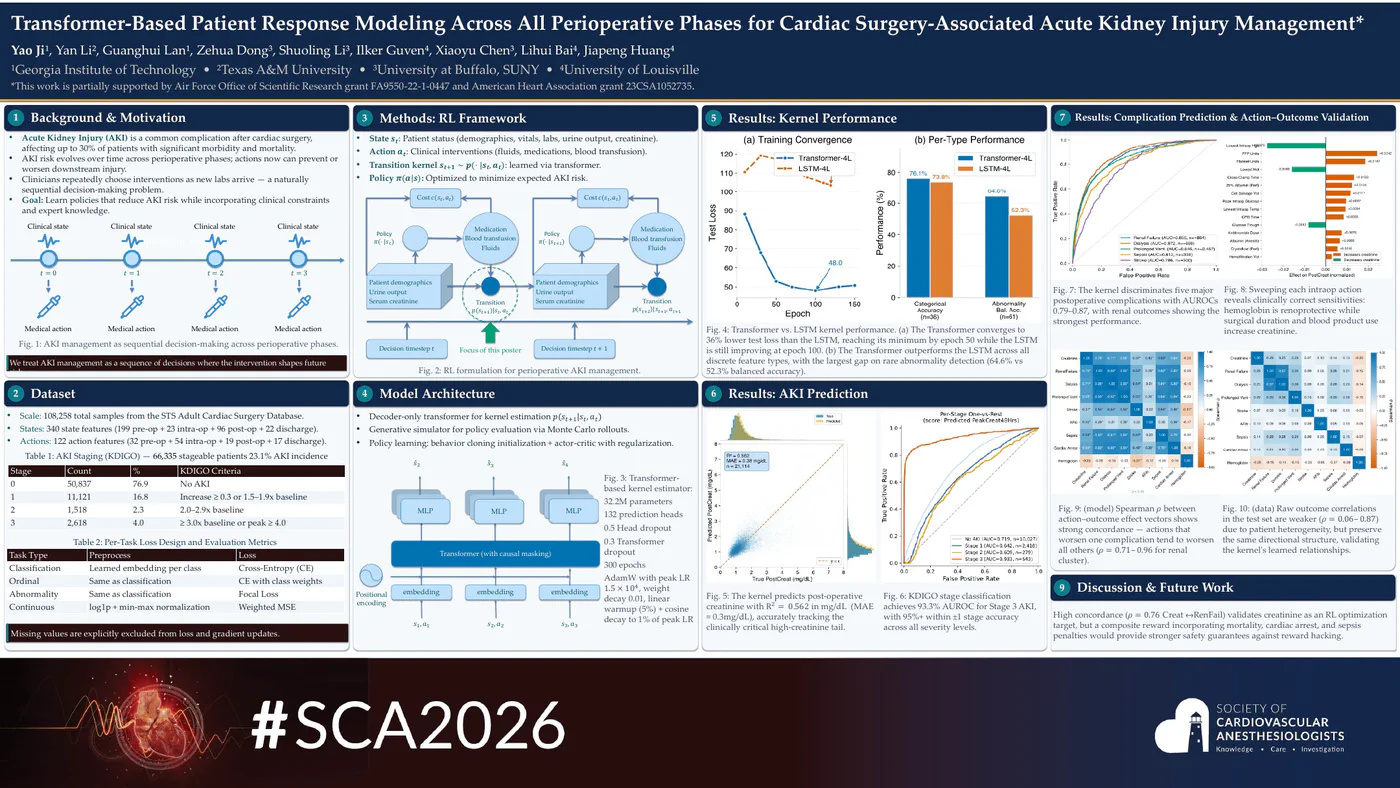
The SCA 2026 conference poster. Sections cover the background and motivation for cardiac surgery-associated acute kidney injury, the dataset of 108,258 adult cardiac surgery admissions, a reinforcement learning framework formulating perioperative management as sequential decision-making, a transformer model architecture, and results on kernel performance, AKI prediction, and complication prediction, closing with discussion and future work.

Transformer-Based Patient Response Modeling Across All Perioperative Phases for Cardiac Surgery-Associated Acute Kidney Injury Management

Transformer-based modeling of patient response across all perioperative phases, built to support sequential clinical decision-making for cardiac surgery-associated acute kidney injury.

  • Healthcare

Yao Ji, Yan Li, Guanghui Lan, Zehua Dong, Shuoling Li, Ilker Guven, Xiaoyu Chen, Lihui Bai, and Jiapeng Huang

Society of Cardiovascular Anesthesiologists Annual Meeting

Nashville, TN, 2026

Poster

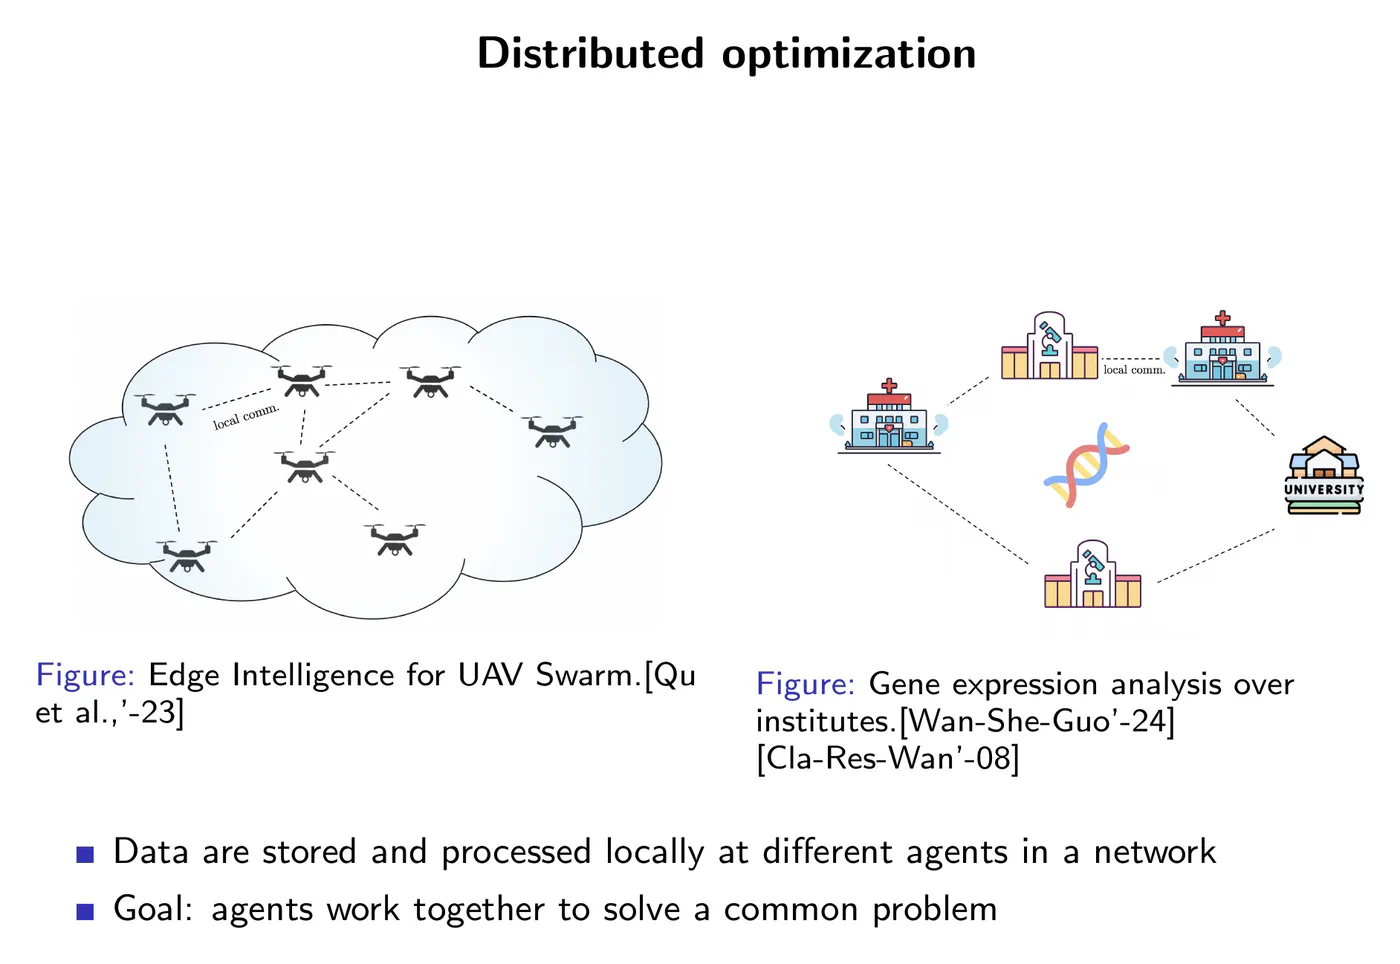
Two motivating settings for distributed optimization. Left: a swarm of UAVs linked by local communication over a mesh network. Right: several hospitals and a university jointly analysing gene expression data over local links. Data stay stored and processed locally at each agent, and the agents work together to solve a common problem.

Distributed Sparse Regression via Penalization

Statistical and computational guarantees for sparse linear regression over a network of agents, formulated as local LASSO losses plus a quadratic penalty on the consensus constraint.

  • Distributed Optimization

Yao Ji, Gesualdo Scutari, Ying Sun, and Harsha Honnappa

Journal of Machine Learning Research

Vol. 24(272), pp. 1–62

2023

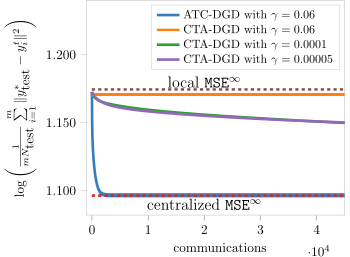
Test mean squared error against the number of communications. ATC-DGD with step size 0.06 drops sharply within a few thousand communications and settles on the centralized mean squared error. CTA-DGD with the same step size stalls at the local mean squared error, and CTA-DGD with much smaller step sizes, 0.0001 and 0.00005, decreases only slowly and is still far above the centralized level after 45,000 communications.

Distributed (ATC) Gradient Descent for High Dimension Sparse Regression

First statistical study of adapt-then-combine distributed gradient descent, showing linear convergence to centralized statistical precision with communication growing only logarithmically in the ambient dimension.

  • Distributed Optimization

Yao Ji, Gesualdo Scutari, Ying Sun, and Harsha Honnappa

IEEE Transactions on Information Theory

Vol. 69(8), pp. 5253–5276

2023

Teaching

Teaching Experience

Georgia Institute of Technology, ISyE

Advisor

  • ISyE 4106 Senior Design is the flagship capstone experience of Georgia Tech’s Industrial Engineering undergraduate program. Georgia Tech has described Senior Design as its “most important and most challenging undergraduate course,” and its projects have repeatedly received national recognition, including first-place finishes in the IISE Outstanding ISE Capstone Senior Design Project Competition. Fall 2026

Purdue University, Industrial Engineering

Teaching Assistant

  • IE 335: Operations Research Spring and Fall 2023
  • IE 330: Probability and Statistics in Engineering Fall 2022
  • IE 590: Introduction to Optimization Algorithms (graduate-level) Fall 2022

Beijing Normal University, School of Mathematical Sciences

Co-Lecturer

  • Large Deviation Theory Spring 2018
  • Brownian Motion Fall 2017
  • Random Walk in Random Environment Spring 2017
  • Galton–Watson Branching Process Fall 2016

Teaching Assistant Outstanding Teaching Assistant Award

  • Measure Theory I Fall 2017 and Fall 2018
  • Measure Theory II Spring 2017 and Spring 2018
  • Stochastic Calculus for Finance (graduate-level) Fall 2016

Outreach